A repeatable directory engine, live across the UK and US and expanding, that can be pointed at any listing market
Systems thinking and repeatability: one engine, built once, pointed at any listing market.
The situation
Directory content is valuable to readers and expensive to produce by hand, and the same underlying structure repeats across dozens of unrelated verticals: parks, trails, restaurants, coworking spaces. Nobody was treating that as one problem.
What I did
I designed the data model, the content generation approach and the page structure, built the base platform, populated it at global scale, and integrated advertising as the revenue model. Dog Park Explorer is the specific site; the actual product is the engine underneath it. If a reader comes away thinking this is a project about dog parks, the page has failed — the point is the machine that can produce a site like this in a fraction of the original build time.
System diagram
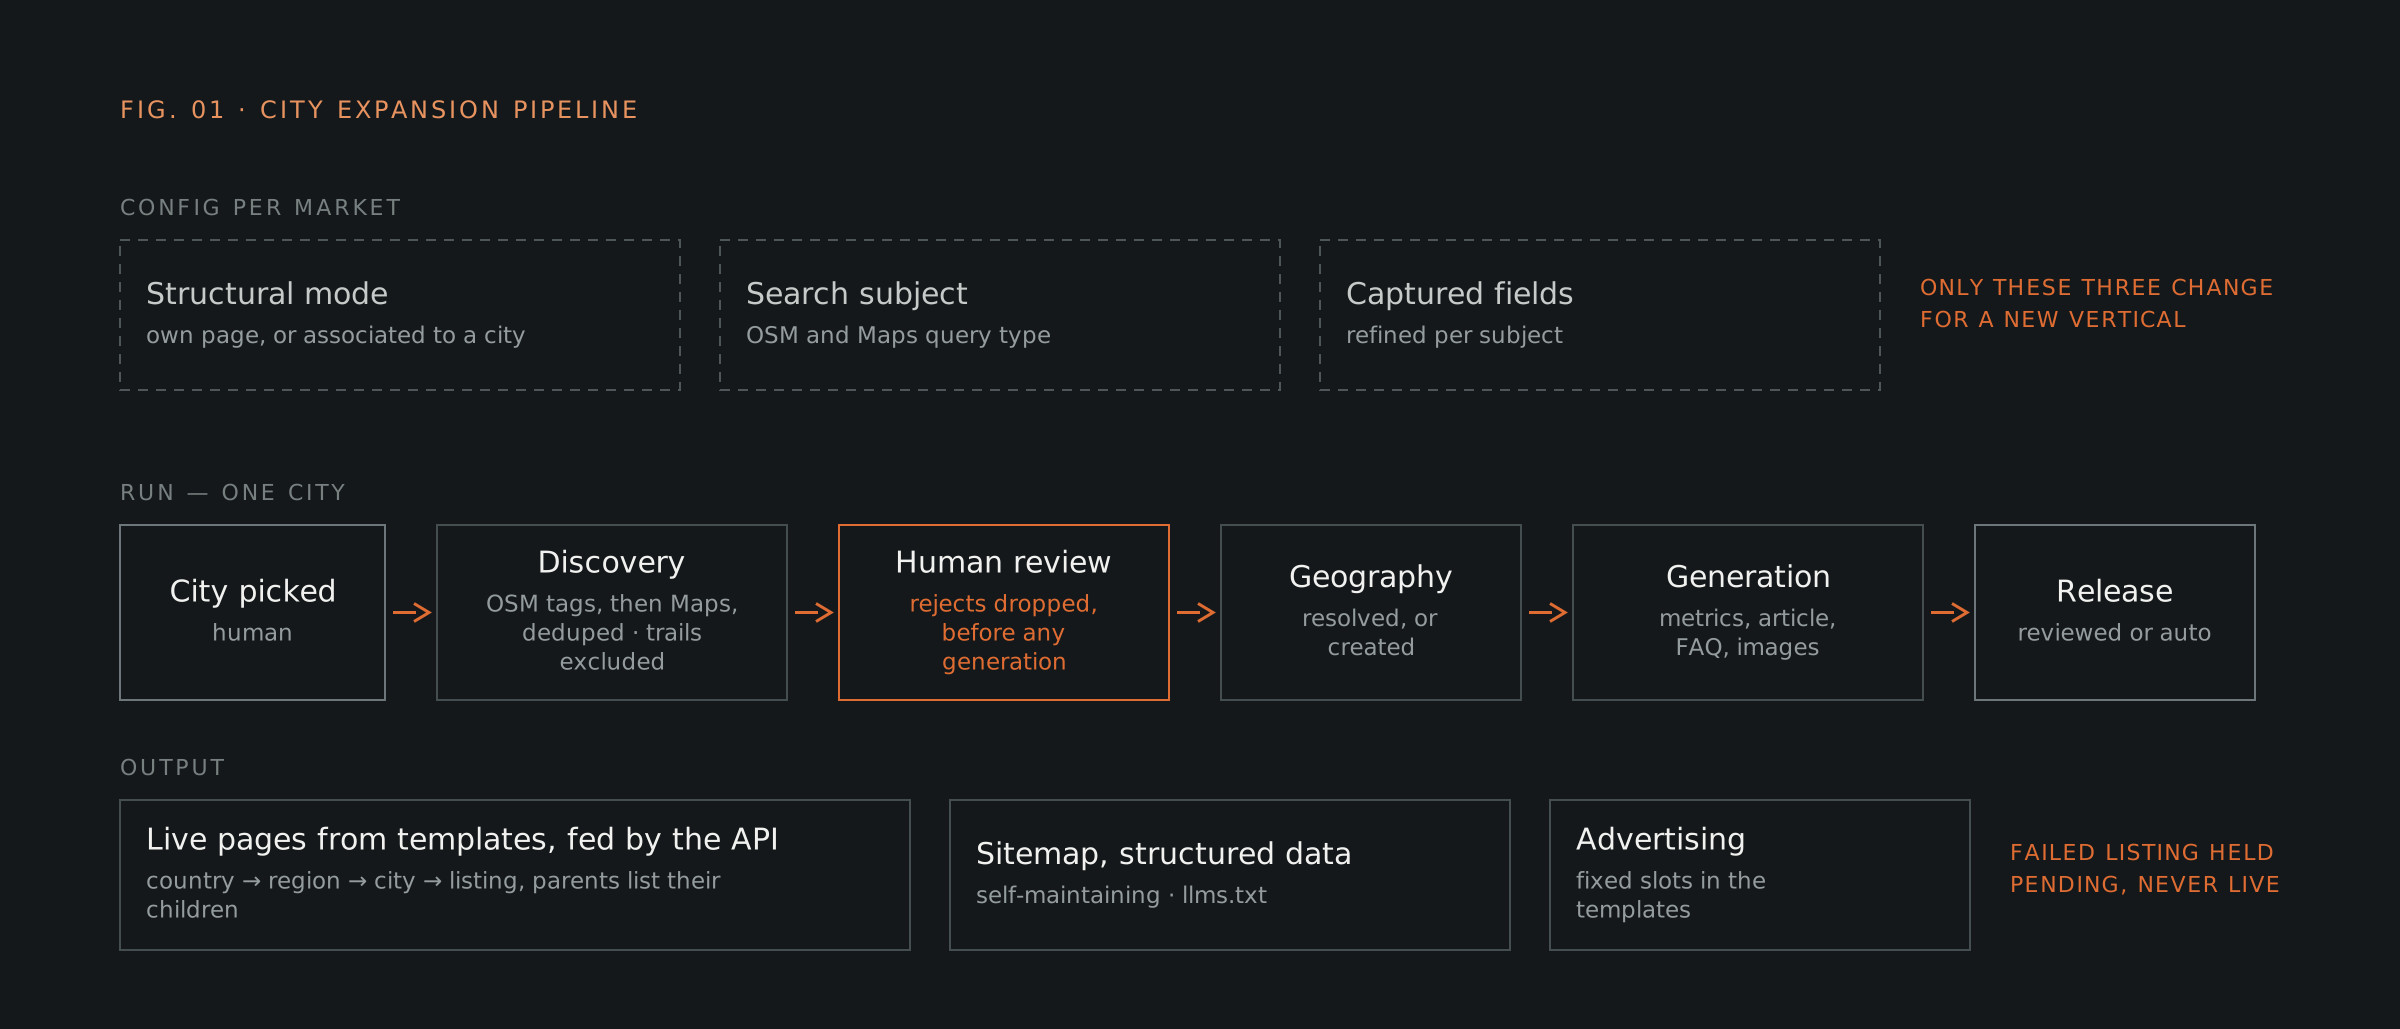 , expand
The engine is only visible in three places
The pipeline decides which city runs next and what a person has to approve before it can publish. None of that is visible as a pipeline, so it surfaces as three screens: the run queue, the review step that holds a candidate back, and the listing a reader eventually lands on.
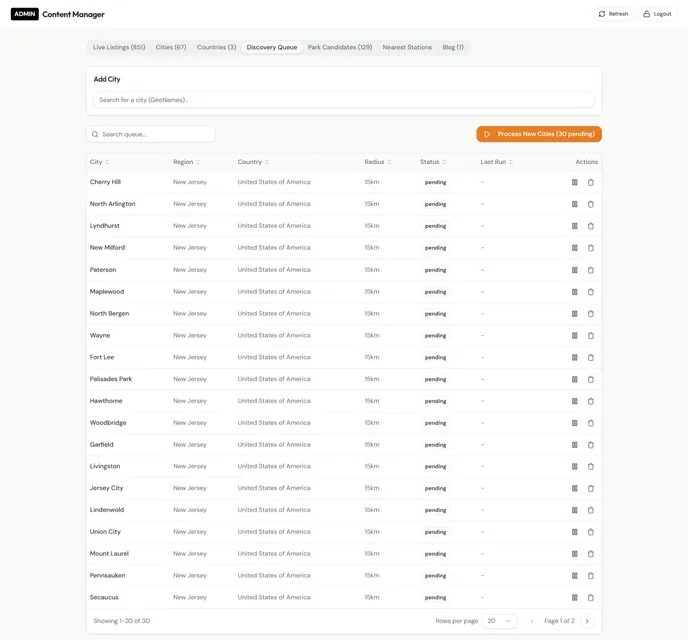
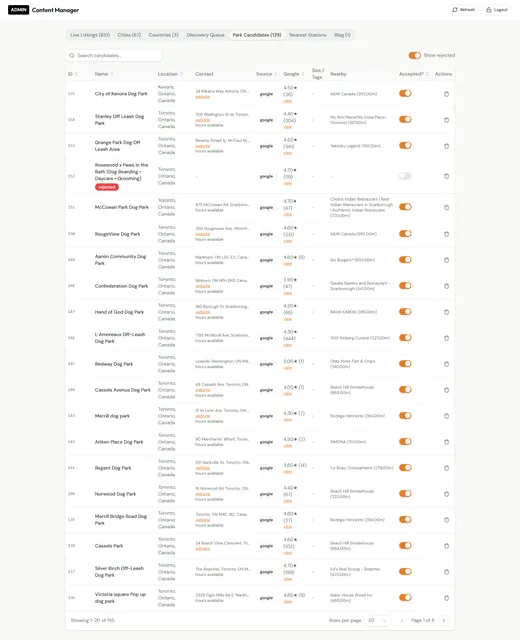
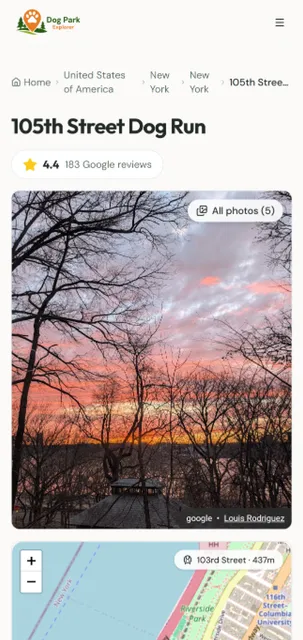
FIG. 02 — CITIES QUEUED, LISTINGS REVIEWED BY A PERSON, A PUBLIC PAGE OUT.
Key decisions and tradeoffs
Four decisions that shaped the engine, the alternative in each case, and what the choice cost.
Building a reusable engine rather than a single site
Content generation approach and quality control at volume
Advertising as the revenue model, rather than listing fees or subscriptions
Page structure and internal linking decisions made for search and AI visibility
Current status
About 800 parks are live today, across the UK and the US, and neither country's coverage is complete yet — that's deliberate. The templates are going through Google's own site quality review before wider rollout and advertising switch on, so coverage is staged rather than a limit of the engine itself, which is already built to produce whichever market or vertical comes next: hiking trails, vegan restaurants, coworking spaces, in a fraction of the time the original build took.
Stack and timeline
The frontend is a React 19 and TypeScript single page app (Vite, Tailwind, shadcn/ui, TanStack Query for server state), talking to a Node.js and Express API deployed as Vercel serverless functions rather than a persistent server. Data lives in a Supabase hosted PostgreSQL database through Drizzle ORM, and listing photos are pulled from Google Places and re-hosted permanently on Cloudflare R2 — the originals expire after a week, so a quarterly refresh job keeps them available without re-fetching on every page load. Cloudflare Turnstile filters bot traffic, Upstash Redis handles rate limiting across the stateless serverless functions, Resend sends notification email, and OpenAI drafts blog content for review before it publishes. Advertising runs through Google AdSense, loaded only after cookie consent.
The build split into a base platform phase, a population phase to bring the directory to scale, and the current phase: passing Google's review before opening up full coverage and new verticals.
Have a system that half works and nobody wants to touch?
A systems review puts the situation, the cost and the options in writing.